
Free AI models for building websites
Every free text model on Groq and OpenRouter got the same two tasks from the openconstructor editor: build a coffee-shop landing page, and answer a short CSS question. We measured the time, checked the answer format and looked at the result.
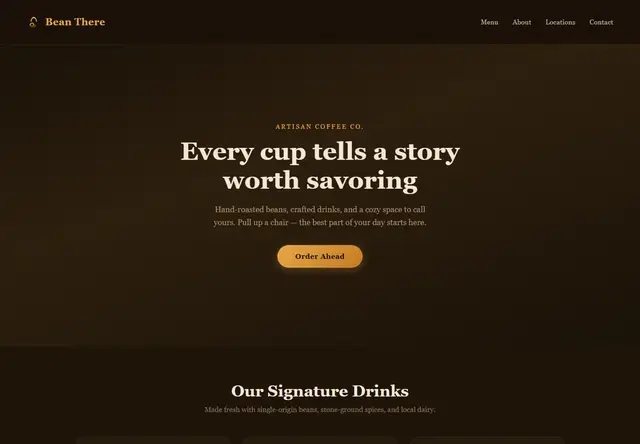
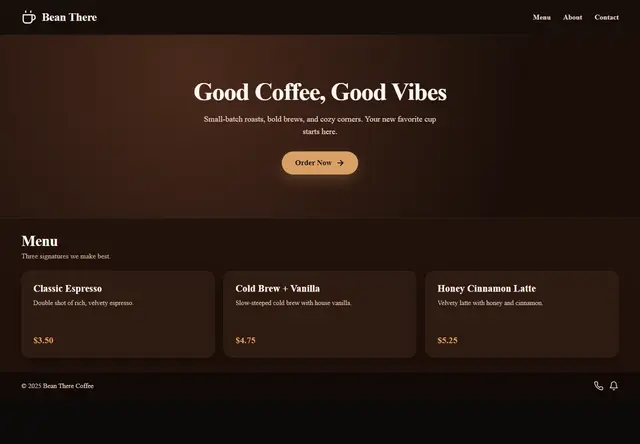
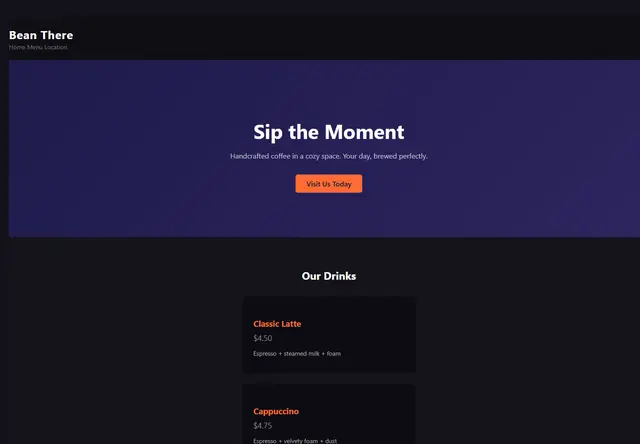
Clearly the nicest pages. On the free plan — about one page a minute.
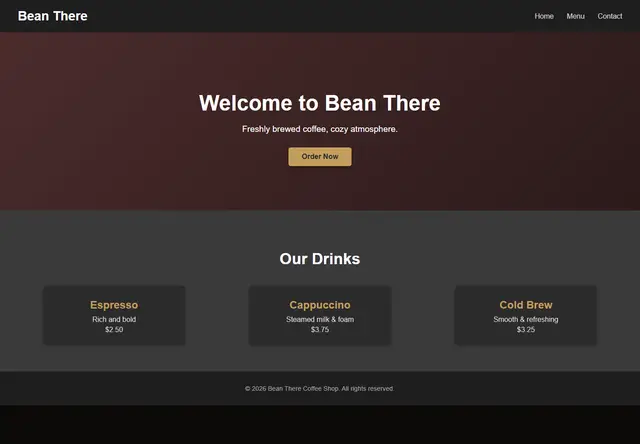
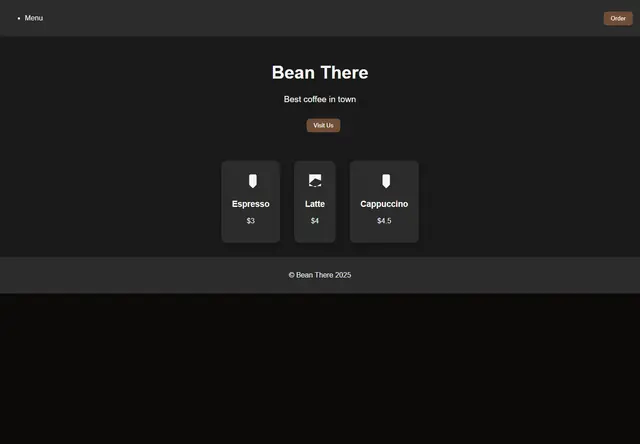
A full page in ~2 seconds, never broke the format. What the free AI uses first.
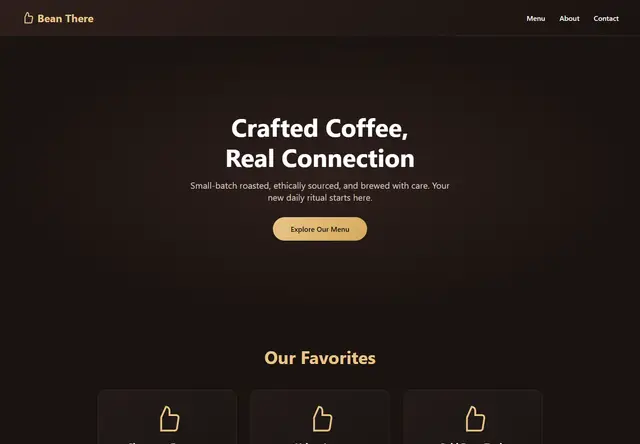
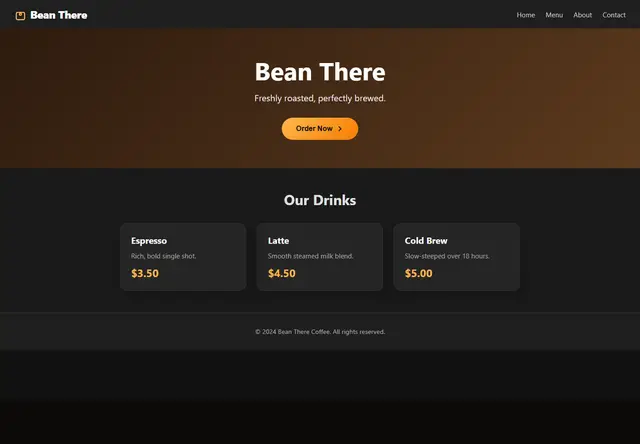
Polished result with icons; takes ~40 seconds.
Free models — rating
Score = design 65% + speed 20% + reliability 15%. Design is a 0–10 visual grade of the landing page; speed is the time to the full answer; reliability counts broken formats and rate limits.
| # | Model | Score | Design | Page | Question | Notes |
|---|---|---|---|---|---|---|
| 1 | Qwen 3.8 27BGroq · qwen/qwen3.8-27b | 8.4 | 9 | 5.0 s | — | Best design by far: serif headings, icons, warm palette. Free plan allows about one page a minute; the next request right after gets rate-limited. |
| 2 | Nemotron 3 Ultra 550BOpenRouter · nvidia/nemotron-3-ultra-550b-a55b:free | 7.8 | 8.5 | 38.0 s | 5.7 s | Polished, complete page with icons and footer. Slow, but reliable. |
| 3 | GPT-OSS 120BGroq · openai/gpt-oss-120b | 7.4 | 6 | 2.3 s | 0.7 s | Clean and simple. The fastest dependable choice — the default for the free AI. |
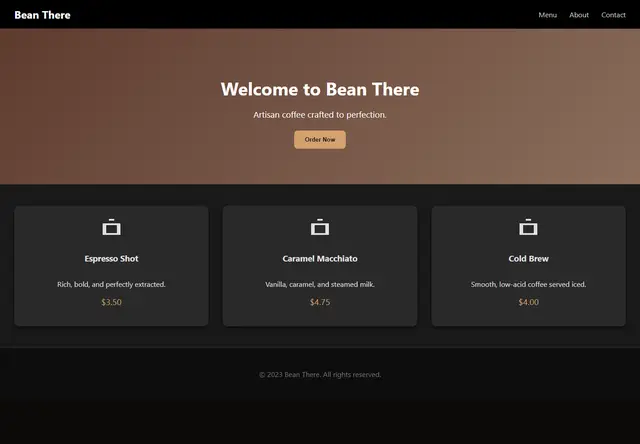
| 4 | North Mini CodeOpenRouter · cohere/north-mini-code:free | 6.9 | 6.5 | 17.2 s | 1.2 s | Neat cards with icons; plain hero. |
| 5 | Flint v1.0OpenRouter · recursive/flint-v1.0:free | 6.8 | 7.5 | 40.5 s | 4.1 s | Tasteful serif look, good menu cards. Slow. |
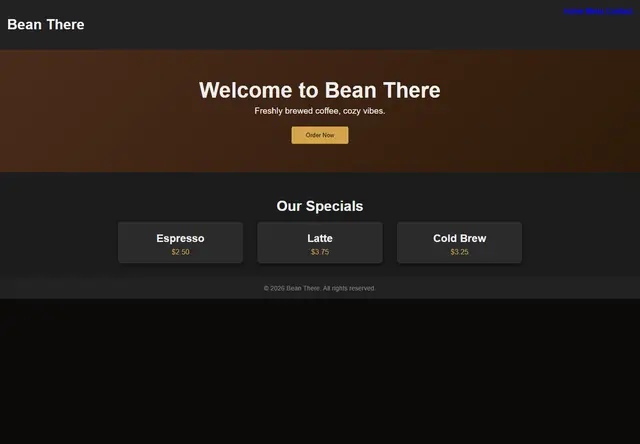
| 6 | GPT-OSS 20BGroq · openai/gpt-oss-20b | 6.8 | 5 | 1.1 s | 0.4 s | Fastest of all, but plainer; menu links came out unstyled blue. |
| 7 | LFM 2.5 2.6BOpenRouter · liquid/lfm-2.5-2.6b:free | 6.7 | 5.5 | 5.1 s | 0.9 s | Tiny and quick; bold but generic colours. |
| 8 | Nemotron 3.5 Super VLOpenRouter · nvidia/nemotron-3.5-super-vl:free | 6.5 | 6.5 | 33.4 s | 4.1 s | Solid, a bit plain. Can also read screenshots. |
| 9 | Nemotron 3 Nano Omni 30BOpenRouter · nvidia/nemotron-3-nano-omni-30b-a3b-reasoning:free | 5.3 | 4 | 16.8 s | 5.1 s | Very small layout, little content. |
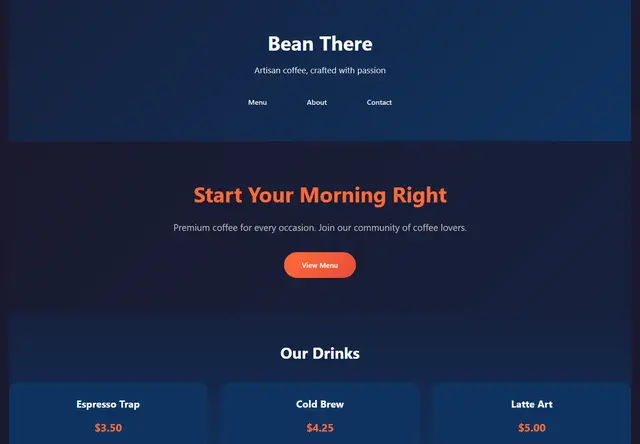
| 10 | Nemotron 3.5 LightningOpenRouter · nvidia/nemotron-3.5-lightning:free | 5.2 | 5 | 43.0 s | 10.8 s | Narrow menu column, slow despite the name. |
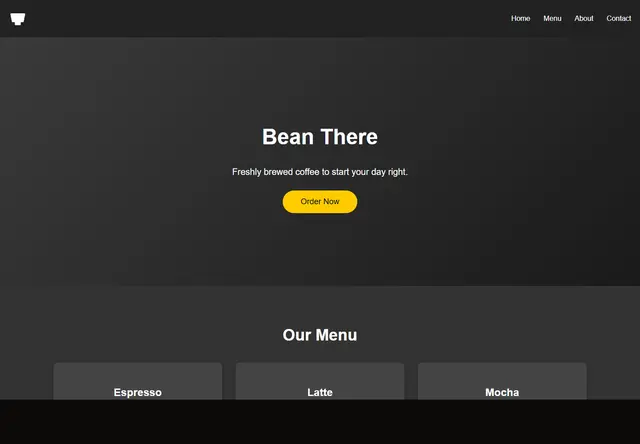
| 11 | Dots 3 Note (preview)OpenRouter · dots-studio/dots-3-note-preview:free | 4.5 | 4 | 70.2 s | 10.0 s | Very slow; the menu section came out cut off. |
Not rated this time:
- Gemma 4 31B
google/gemma-4-31b-it:free— busy at the provider (429) in every attempt - Gemma 4 26B
google/gemma-4-26b-a4b-it:free— busy at the provider (429) in every attempt - Xing 4.0 29B
xingchen-agi/xing4.0-29b-a4b:free— answered the question; the page request was rate-limited - LFM 3 1.7B
liquid/lfm-3-1.7b:free— ran out of tokens and broke the answer format
What they built
The landing pages exactly as each model returned them (top of the page).
Cheapest paid models — cost per page
Prices per 1 million tokens on OpenRouter. A typical landing page is about 2,000 tokens in and 3,500 out. These were not part of the test above.
| Model | Input / 1M | Output / 1M | One page | Pages per $1 |
|---|---|---|---|---|
GPT-OSS 120Bopenai/gpt-oss-120b | $0.025 | $0.094 | $0.0004 | 2,638 |
Mistral Small 24Bmistralai/mistral-small-24b-instruct-2501 | $0.050 | $0.080 | $0.0004 | 2,631 |
Qwen 3.7 Flashqwen/qwen3.7-flash | $0.030 | $0.130 | $0.0005 | 1,941 |
GPT-OSS 20Bopenai/gpt-oss-20b | $0.030 | $0.130 | $0.0005 | 1,941 |
DeepSeek V4 Flashdeepseek/deepseek-v4-flash | $0.091 | $0.182 | $0.0008 | 1,221 |
Mistral Small 3.2mistralai/mistral-small-3.2-24b-instruct | $0.075 | $0.200 | $0.0008 | 1,176 |
Qwen3 32Bqwen/qwen3-32b | $0.080 | $0.280 | $0.0011 | 877 |
GPT-5 nanoopenai/gpt-5-nano | $0.050 | $0.400 | $0.0015 | 666 |
Gemini 2.5 Flash-Litegoogle/gemini-2.5-flash-lite | $0.100 | $0.400 | $0.0016 | 625 |
Claude Haiku 5.5anthropic/claude-haiku-5.5 | $0.100 | $0.500 | $0.0019 | 512 |
GLM 5.3 Flashz-ai/glm-5.3-flash | $0.150 | $0.500 | $0.0021 | 487 |
How it was tested
- The editor's own instructions: a one-line JSON header, then the HTML and CSS in one code block; questions answered as text, without building anything.
- One attempt per model and task, low reasoning effort where supported, up to 8,000 output tokens, pauses between requests.
- “Format” means the answer could be placed on the canvas (or shown as text for the question) without a retry.
- Free tiers change often: models appear, disappear and get rate-limited. Groq removed Llama 3.3 70B before this test.